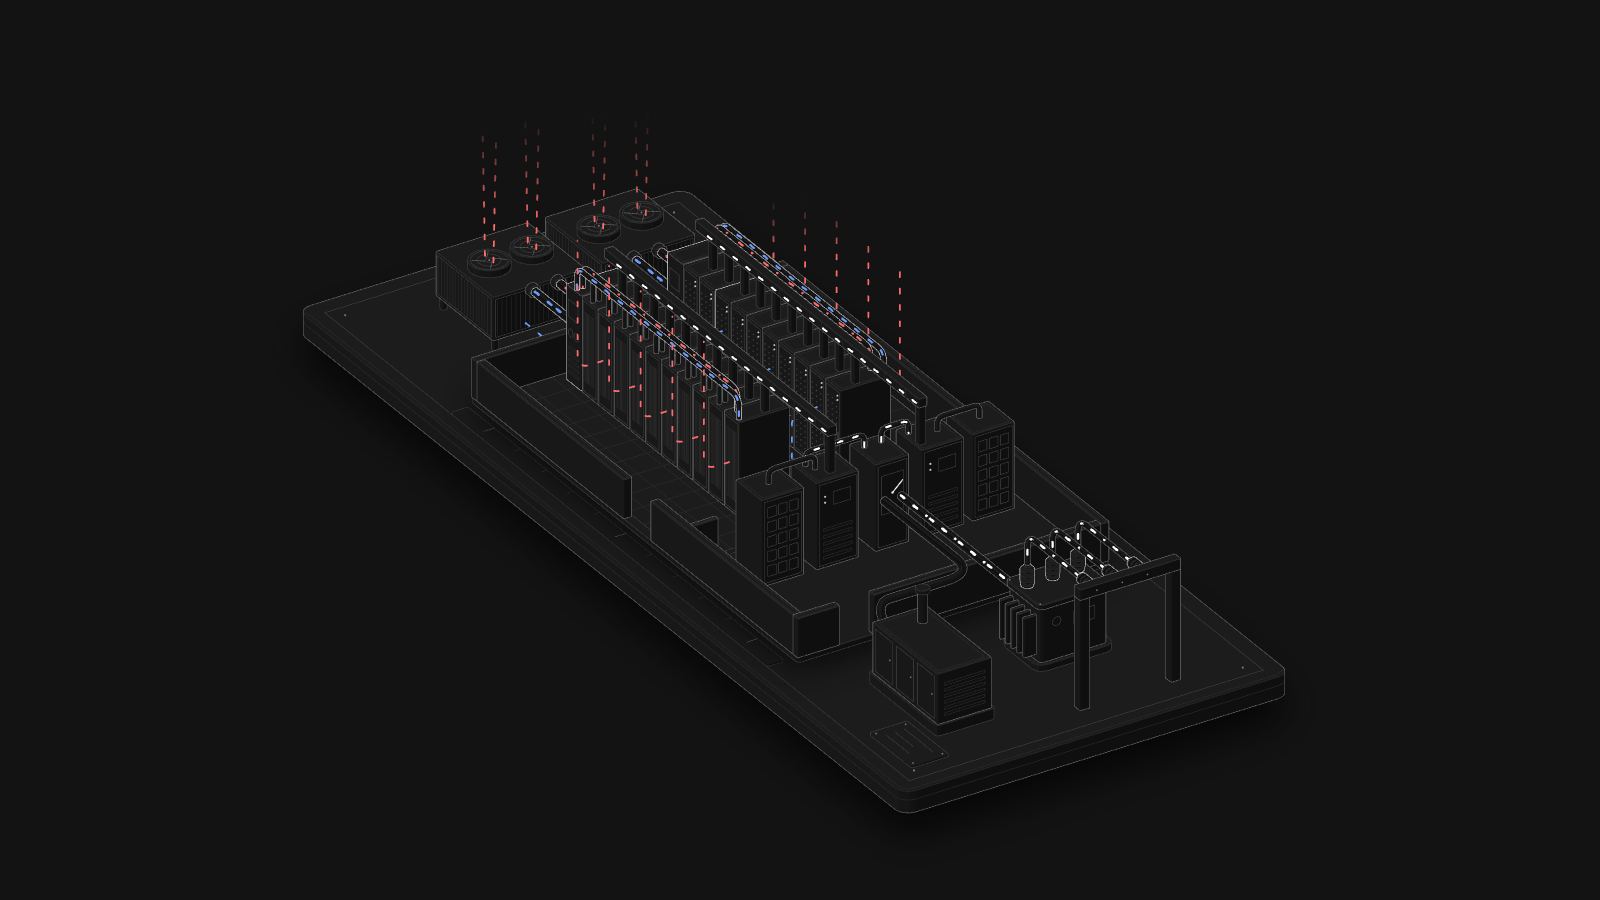
Quatre figures à manipuler pour voir ce qui fait tourner un datacenter d'IA : le bâtiment entier et ses flux, des serveurs de 10 kW, une boucle d'eau qui emporte 120 kW par rack, et une chaîne électrique qui ne laisse jamais le rack sans courant.
Je bosse presque exclusivement sur macOS depuis plus de dix ans. Depuis une semaine, j’utilise Omarchy pour développer des applications sur ma tour PC. J’ai aussi profité des derniers jours pour l’installer et le tester sur un Mac mini Intel de 2018 avec puce T2.
Serveur Linux sur un Mac mini T2, accès privé, Discord, veille IA/dev et métadonnées Gmail en lecture seule : ce que j’ai construit, ce qui a cassé et ce qui reste à valider.
Would /v1/decisions (label probabilities from one prompt pass, no generation) be useful to you in #TensorFold’s native engine? Working on Flash Next CUDA (DGX Spark) first; the hook would be shared for others models. @IntelAI Arc B70 users, interested too? cc @ashxhart #LocalAI
An #NVIDIA model, on an #Intel GPU, running a #TensorFold engine, piloting a @pollenrobotics duck. This is either the future of physical AI or the start of a very nerdy sitcom 🦆 Yes, I'm porting Bolt E4B to the B70 now 🐤 https://t.co/O9oCKj693K Coin ! #Microduck
Gemma 4 E4B (NVIDIA Nemotron 3.5 Bolt E4B) now runs on the Intel Arc Pro B70 in #TensorFold main. 4-bit, on one card: 6,772 tok/s prompt, 135.6 tok/s decode. Served chat: 140 / 253 / 426 tok/s at 1 / 2 / 4 streams. Build from main for now; it isn't in a release yet. More prefill
Publication avec citation · Modèles & recherche · Infra & self-host
Gemma 4 on Intel Arc is now on this version 1.2.0 🎉🎃 Next version will introduce 2x to 2.8x in prefill speed, more than 15k tok/s on the same GPU! @intel @fragtalife #LocalAI
Publication avec citation · Modèles & recherche · Infra & self-host
🚀 Proud of this PR merged! Prompt processing for Gemma 4 E4B is now 2-2.6× faster on Intel Arc Pro B70. Massive win for local AI workloads on Intel GPUs: less waiting, more tokens🔥 #OpenSource #LocalAI #IntelArc #Tensorfold
For fun, and since some of you do robotics: @liquidai LFM3-VL-2B on a single @intel Arc Pro B70, on a work-in-progress branch I’m preparing for #TensorFold. 55 ms to first token on a fresh image, ~270 tok/s for one stream, ~4,500 tok/s served at 32 concurrent streams. And the
Publication avec citation · Modèles & recherche · Agents & automatisation · Infra & self-host
Proud to be part of this great release. More to follow on XPU: Qwen3.8-27B attention merge with 16 subgroups per head, bit-identical. Some tweaks for more tok/s. #LocalAI @intel